Senior Site Reliability Engineer (Remote - India)
- Location
- Remote
- Type
- Full-time
The role
We are seeking an accomplished Senior Site Reliability Engineer (SRE) to lead the design, implementation, and evolution of highly available, scalable, and resilient systems across our multi-cloud infrastructure. In this senior role, you will drive architectural decisions, establish reliability standards, and mentor teams while ensuring operational excellence across complex distributed systems. You will partner with engineering leadership, development teams, and product stakeholders to shape infrastructure strategy, implement sophisticated automation, and champion a culture of reliability engineering.
At Axelerant, we are committed to fostering an environment where innovation and operational excellence thrive. As a Senior SRE, you'll tackle sophisticated, large-scale challenges using cutting-edge technologies across AWS and Azure platforms. You will lead critical initiatives that impact system reliability at scale, architect solutions for complex infrastructure problems, and guide teams in adopting industry-leading practices that drive meaningful improvements across our entire technology ecosystem.
What you will own
- Architect and implement highly reliable, scalable, and cost-effective infrastructure solutions for mission-critical applications across multi-cloud environments (AWS and Azure).
- Lead the definition and refinement of service level objectives (SLOs), service level indicators (SLIs), and error budgets, establishing reliability standards across the organization.
- Design and implement sophisticated Infrastructure as Code (IaC) solutions using Terraform, Ansible, and Azure Resource Manager (ARM) templates or Bicep.
- Drive automation strategies to eliminate toil, improve operational efficiency, and enable self-service capabilities for development teams.
- Lead incident response efforts, conduct thorough post-incident reviews, and implement systemic improvements to prevent recurrence.
- Champion cloud-native architectures and modern reliability practices, serving as a technical advisor for infrastructure and platform decisions.
- Mentor junior SREs and engineers, fostering a culture of reliability, observability, and continuous improvement.
- Participate in and help optimize the on-call rotation, ensuring sustainable practices and effective escalation procedures.
- Establish and maintain comprehensive documentation standards, runbooks, and knowledge repositories that enable team autonomy and effective incident response.
- Design and implement advanced monitoring, logging, and alerting strategies using observability platforms to enable proactive issue detection and resolution.
- Lead container orchestration initiatives using Kubernetes (AKS, EKS) and implement sophisticated deployment strategies including blue-green, canary, and progressive delivery patterns.
- Ensure security, compliance, and governance standards are embedded throughout the infrastructure lifecycle, implementing security-as-code practices.
- Drive capacity planning, performance optimization, and cost management initiatives across cloud platforms.
- Collaborate with architecture and security teams to establish platform standards, reference architectures, and best practices.
What you bring
- 5+ years of proven experience as a Site Reliability Engineer or similar role, with demonstrated expertise in designing, implementing, and operating large-scale, distributed systems.
- Deep expertise in Infrastructure as Code (IaC) with Terraform and Ansible, including module development, state management, and multi-environment orchestration.
- Extensive hands-on experience with both AWS and Azure cloud platforms, including advanced services, networking, and security features in both environments.
- Expert-level knowledge of container orchestration with Kubernetes, including architecture, custom resource definitions (CRDs), operators, service mesh implementations, and production-scale cluster management.
- Advanced proficiency in Linux system administration, performance tuning, and troubleshooting complex system-level issues.
- Proven experience implementing GitOps workflows using ArgoCD, Flux, or similar tools, including advanced deployment patterns and progressive delivery.
- Deep understanding of observability principles and hands-on experience with tools such as Prometheus, Grafana, Datadog, Azure Monitor, or the ELK stack.
- Expert knowledge of networking concepts, including load balancing, CDNs, DNS, VPNs, service mesh architectures, and distributed systems communication patterns.
- Strong programming and scripting capabilities in Python, Bash, Go, or PowerShell, with the ability to develop custom tooling and automation frameworks.
- Extensive experience designing and optimizing CI/CD pipelines using Jenkins, GitLab CI, Azure DevOps, GitHub Actions, or CircleCI.
- Demonstrated ability to lead incident response, conduct root cause analysis, and drive systemic reliability improvements.
- Excellent communication and leadership skills with proven ability to influence technical decisions and collaborate with stakeholders at all levels.
- Current certification in AWS (Solutions Architect Associate/Professional or equivalent) and Azure (Azure Administrator or Azure Solutions Architect), with practical experience managing production workloads on both platforms.
Good To Have
- Experience with hybrid and multi-cloud networking strategies, including ExpressRoute, Direct Connect, and cloud interconnects.
- Knowledge of serverless architectures on AWS (Lambda) and Azure (Functions, Logic Apps) and their operational considerations.
- Proven experience with disaster recovery planning, business continuity, and implementing multi-region active-active architectures.
- Understanding of machine learning operations (MLOps), data pipeline orchestration, and supporting ML workloads in production.
- Experience with service mesh technologies such as Istio, Linkerd, or Consul.
- Familiarity with chaos engineering principles and tools like Chaos Monkey or Gremlin.
- Experience with configuration management at scale and policy-as-code tools like Open Policy Agent (OPA).
- Knowledge of FinOps principles and cloud cost optimization strategies.
What Would Success Look Like For You?
Success in this role means establishing and maintaining industry-leading reliability standards, consistently achieving or exceeding SLOs, and driving strategic initiatives that significantly enhance system resilience and operational maturity. You will be recognized for your technical leadership, ability to architect solutions that prevent classes of incidents, your impact on team capability through mentorship, and your contribution to establishing a robust reliability engineering culture across the organization.
Your Work's Impact:
Your contributions will fundamentally shape the reliability, performance, and scalability of our platform, directly enabling engineering teams to innovate with confidence and deliver exceptional value to our customers. Your architectural decisions and reliability practices will influence system design across the organization, setting standards that ensure operational excellence at scale.
Why Axelerant
Why a Senior Site Reliability Engineer (Remote - India) should choose Axelerant?
The role is only half of it. The other half is whether the company is built for the way you do your best work, and whether that claim holds up once you are in.
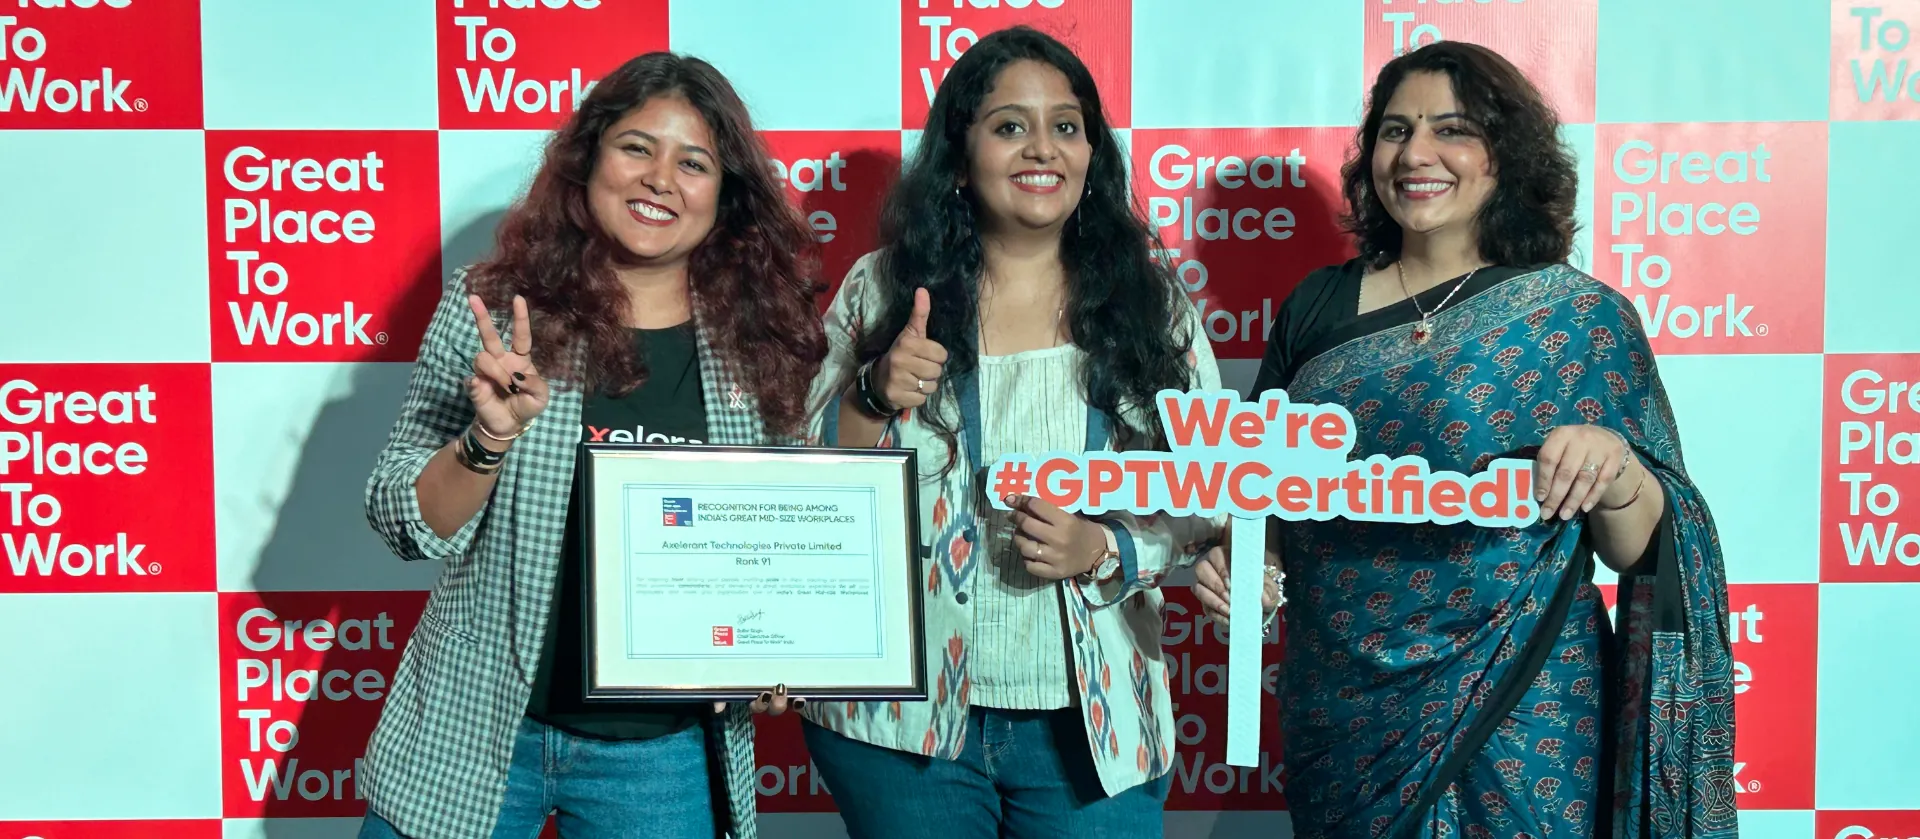
Great Place To Work certified
Named one of India's Best Workplaces in Health and Wellness.
Four values underneath
You see them every day, from leave granted without questions when life happens, to performance coaches, mentors, and wins celebrated in public.
Remote is not a perk here
Axelerant has been remote-first since 2012, years before it was common. It is not a benefit you negotiate for, it is how the company is built.
You shape it yourself
A two-hour overlap with your team is the only fixed point. You are measured on what you ship, not hours online.
150+ people, 12 countries, no middle layer
The team is small on purpose. That means you work directly with client leadership, not behind layers of account managers.
You own it, ambiguity included
You are trusted with real scope early. Systems carry the repetitive delivery work, which leaves you the ambiguous, judgment-heavy calls. That is what we hire for.
You grow by the scope and outcomes you own, not by rungs on a ladder. There is no crowd to disappear into, and no title to wait for.